CamusGPT
A fine-tuned 12B Camus persona that keeps his biography in a retrieval layer, so a wrong fact is a data bug and not a retrain.
The project splits the problem in two: the weights are trained once to make the model speak and behave like Camus, and everything it knows about his life is retrieved at query time from a knowledge base mined from biographies and his own notebooks. A wrong fact is a data edit, not a retraining job.
Retrieval is the part that kept needing work. It started as one flat boost for hand-verified facts, which flooded unrelated prompts. It ended as BM25 fused with dense vectors by reciprocal rank, a cross-encoder reranking the top 30, and a small identity card in the prompt so the cat and the dogs are right even when retrieval misses. The judge scores 34 probes over 10 categories after every change, keyed to the commit, so a retrain cannot quietly make things worse.
The 12B build beat the 8B one, factuality 4.06 against 3.44, and it still confabulates trivia: it lists works as a refusal about half the time, invents a title or two, and calls the dogs cats. Those are weights problems, and the next retrain is scheduled around them.
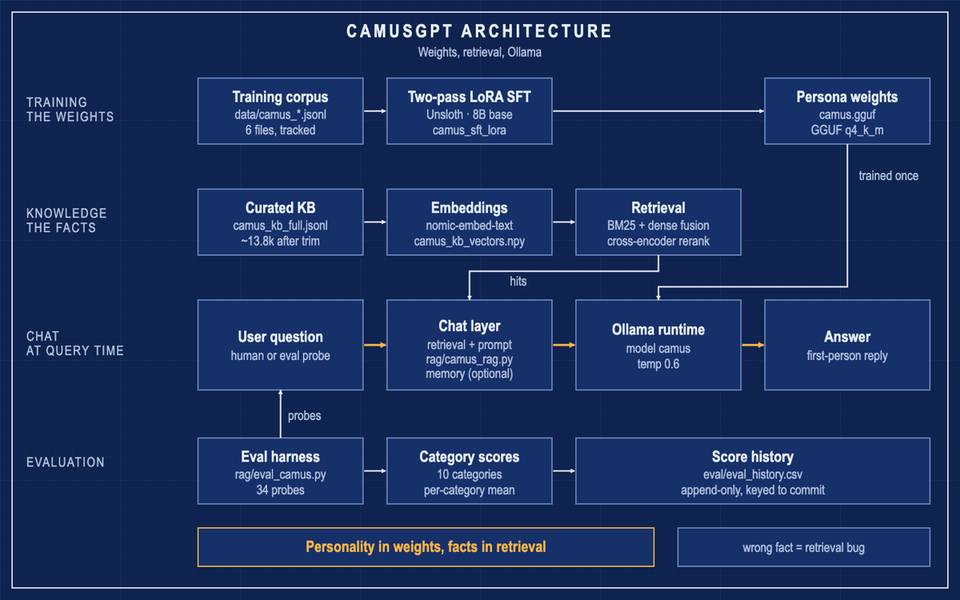
- 1 Identity card About 230 tokens of verified facts sit in the prompt, so trivia cannot miss.
- 2 Hybrid retrieval BM25 and dense fused by reciprocal rank, then a cross-encoder reranks the top 30.
- 3 34 probes Ten categories, scored 1 to 5 by a judge, history keyed to the git commit.
- 4 13,794 entries Semantic dedup cut about 19.6k extracted rows down without losing a curated fact.
Overview
What I built
- +Shipped a 12B two-pass fine-tune, judged at factuality 4.06 against 3.44 for the 8B build it replaced.
- +A knowledge base of 13,794 entries holding 109 hand-verified facts, trimmed so those facts surface more often.
- +34 probes across 10 categories, scored through the real chat pipeline and tracked per commit.
- +A memory layer, off by default, that fixed a self-reference probe scoring 0 of 5.
What I rebuilt
- ~Dropped DPO for a second balanced SFT pass after DPO caused mode collapse.
- ~Replaced the flat curated boost with BM25 fused into dense, then a cross-encoder reranker.
- ~Rejected a leaner CORE prompt after a blind A/B: median reply length only moved from 40 words to 38.
Known limitations
- !Asking for a full list of works is bimodal: it refuses to catalogue in about half of runs.
- !It still invents titles for posthumous work, and swaps the dogs out for cats.
- !The public Space is inactive and its code still targets the 8B build.
Decisions
- 1. Facts in retrieval, not in the weights I chose retrieve every biographical fact from a curated knowledge base at query time, Instead of baking his life into the fine-tuned weights, Because an 8B holds a voice well but cannot store thousands of specific facts without confabulating them..
- 2. Balanced SFT, no DPO I chose a second balanced supervised pass with a fresh guardrail adapter, Instead of DPO on adversarial preference pairs, Because DPO caused mode collapse, and every narrow behaviour over-generalized until it was balanced with contrastive examples..
- 3. Let the reranker promote, not decide I chose add the cross-encoder score to cosine, so it cannot sink a strong hit, Instead of letting the reranker set the final order on its own, Because ms-marco scores conversational first-person facts negatively, so a hard rerank lost the pets that dense retrieval had found..
Timeline
| Version | Date | Description |
|---|---|---|
| v0.1.0 | 2026-06 | First commit: files, cleanup and documentation. |
| v0.2.0 | 2026-07 | v1 shipped: 8B on Ollama locally and on a ZeroGPU Space, KB trimmed to 13,794 entries. |
| v0.3.0 | 2026-08 | v2 shipped: 12B two-pass fine-tune, factuality 3.44 to 4.06 on the judged probes. |
| v0.3.0 | 2026-08 | Memory layer added behind a flag, and a blind human A/B harness authored. |
| v0.4.0 | 2026-09 | First blind A/B rejected the lean prompt: median reply length only moved 40 words to 38. |